 www.iqsource.ai
The Four Loops That Replaced Prompt Engineering
Ricardo Argüello, June 25, 2026
Last week, Tom Osman published something that hit 1.1 million views on X. Not a demo of a new model. A single prompt he gave his agent in Codex: define the goal, catalog every feature on the platform as a user story, run a testing loop against every story, then fix every bug. Alone.
The result: 183 user stories, 105 page routes, weeks of manual QA automated in a single overnight cycle.
What Osman did is not advanced prompt engineering. It’s something qualitatively different. He stopped being the person who writes prompts and became the person who builds the system that writes prompts. That is the shift LangChain articulated in its four-loop framework published the same week, and it’s the frame that matters for anyone building AI systems in production.
Loop 1: the agent you already have
The first loop is what almost everyone already has: the agent calls a tool, reads the result, calls another tool, keeps going until the task is done. Give it context, give it tools, let it run until it says finished.
The honest description of staying at this level: you have a more expensive chat window with extra steps. Useful, but not the category change the headlines promise. Loop 1 is the floor.
Loop 2: the one that verifies without you
The second loop is where it starts to matter. The agent finishes a task and instead of presenting you with results for approval, a grader checks those results against a rubric. If the output doesn’t pass, the feedback loops back to the agent and it retries. No human in the loop.
Two types of verification: deterministic for the objective stuff (does the link resolve, does CI pass, does the scope match the instruction) and LLM-as-judge for the subjective (did it actually answer the question, is the tone right, is the solution safe). The cost is real, 2 or 3x more tokens per task. The case LangChain makes is correct: one wrong answer in production costs more than a thousand automated retries.
Loop 2 is where 90% of teams stop. It’s also where most of the uncaptured value sits.
Loop 3: the one nobody has to invoke
Loop 3 does something qualitatively different: the agent stops waiting to be called. A message in a Slack channel triggers it. A webhook from an integration triggers it. A 3am cron triggers it. Nobody opens a terminal. Nobody clicks a button.
At this point the agent stops being a tool you visit and becomes something that lives inside the systems where work already happens. As I’ve argued about AI as infrastructure: infrastructure doesn’t get visited, it sits beneath everything you already do. Loop 3 is the moment an agent becomes infrastructure.
Loop 4: the one that rewrites itself
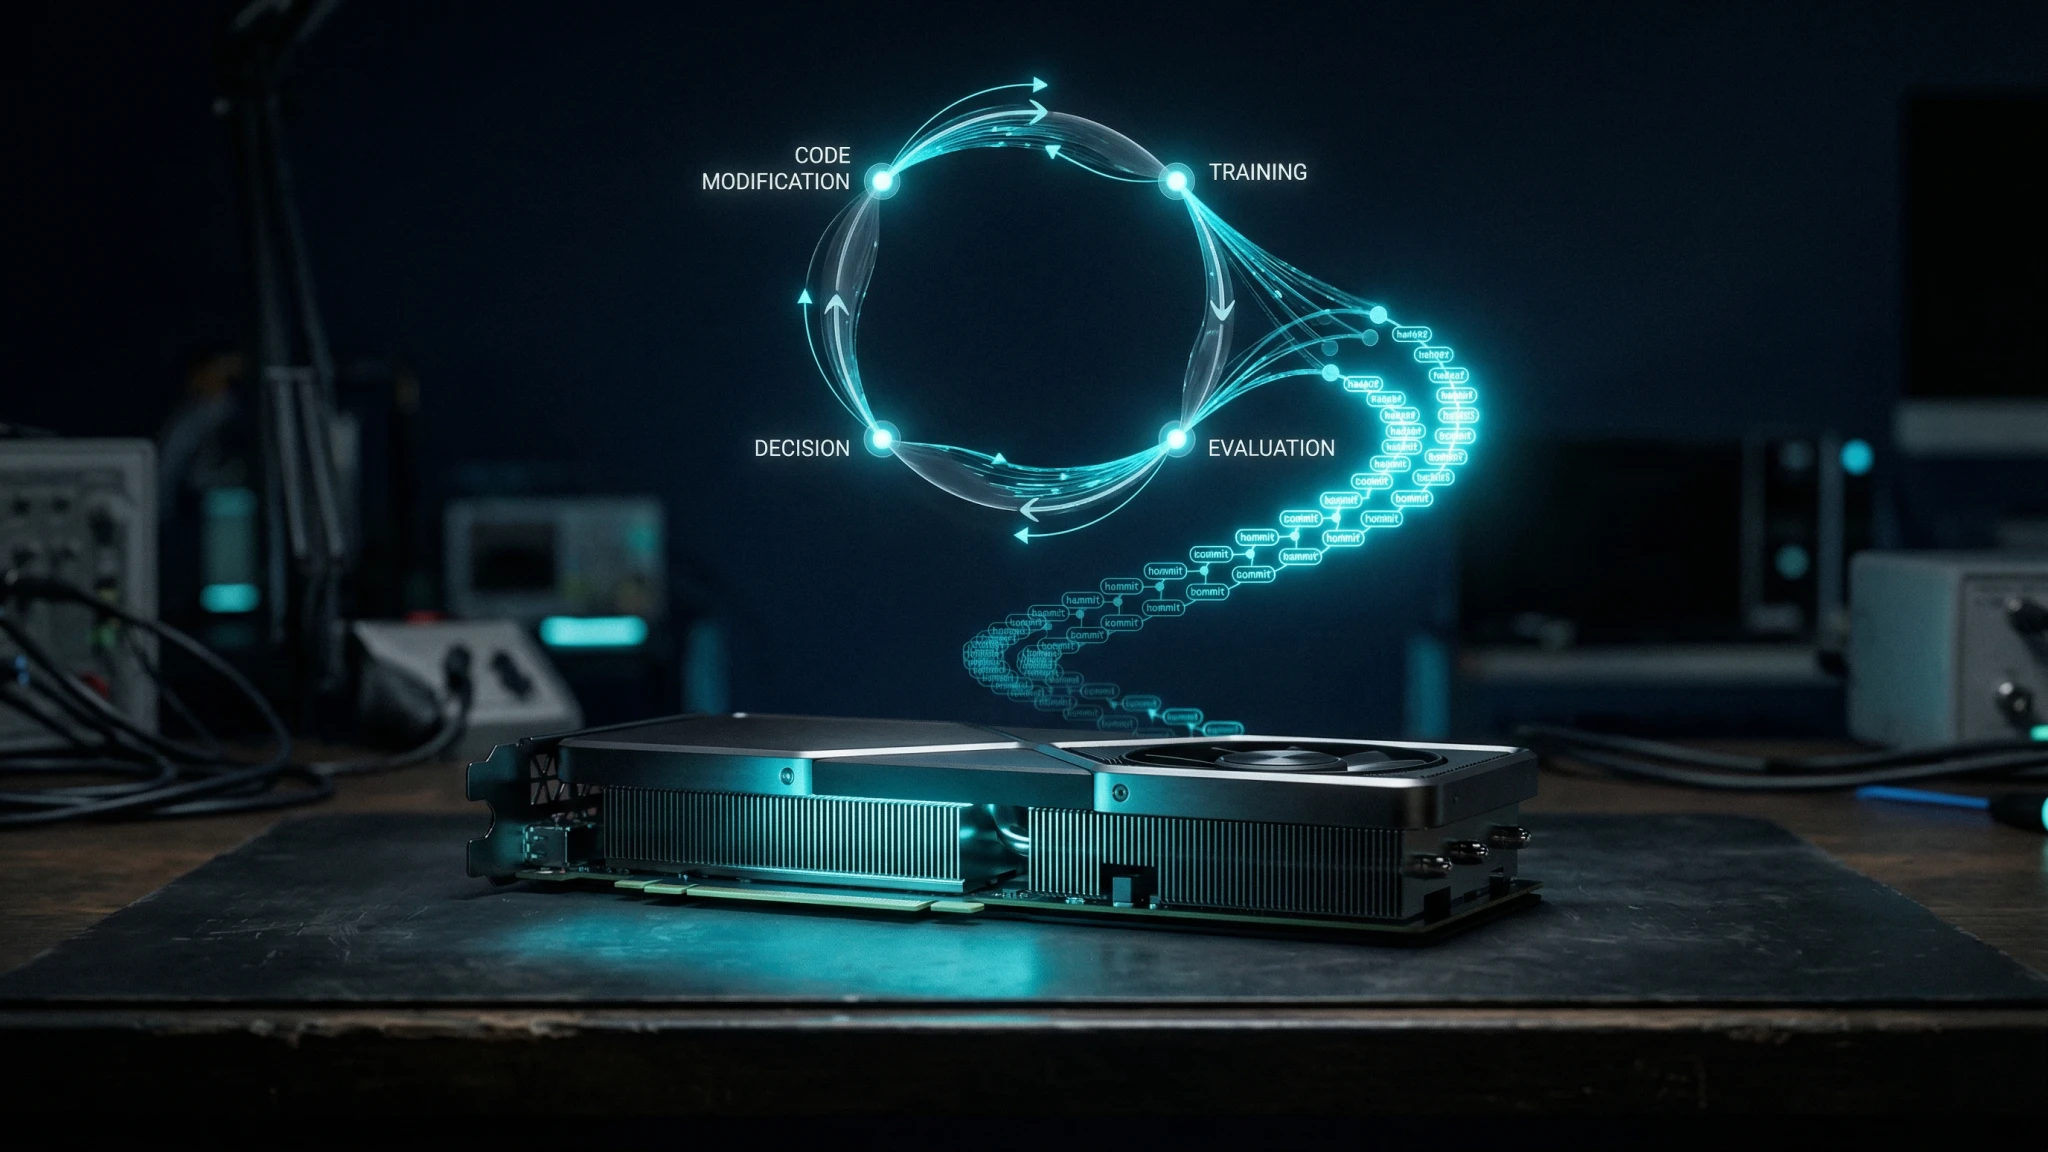
The fourth loop is what Osman triggered and what generates the most skepticism when you describe it. Every execution leaves a trace. An analysis agent reads those traces, identifies recurring failure patterns, systematic biases, the task types where the main agent underperforms, and rewrites the prompt and configuration of loop 1.
The next day, the main agent starts with an improved version of its own instructions. Without anyone touching the code. Without anyone manually reviewing logs.
The math that circulates on this: a 1% daily improvement compounds to 37x in a year. 1.01^365 = 37.8. The details of how that improvement is measured and validated are real work that requires rigor. The principle is sound. An agent with loop 4 active is qualitatively different from the one you shipped on day one.
What this means for building with AI
The question that should concern you most in AI right now isn’t “which model should I use?” It’s “which loop level am I operating at, and what’s stopping me from reaching the next one?”
The model is interchangeable. The loop system you build around it is what compounds. The control system that keeps the agent honest, makes it verify its own output, triggers on events, and improves from its own traces, that’s what isn’t available in a subscription. As I put it in the harness is the moat: the model is a commodity, what you build around it isn’t.
What we build in the implementation phase of AI Maestro is not a loop 1 agent. It’s the full loop system: verification, event activation, traceability for the improvement loop. The difference between a demo that impresses and an agent that keeps getting better after we leave is exactly the difference between loop 1 and loop 4.
Build the loop system, not just the agentFrequently Asked Questions
What are the four AI agent loops and what do they do for enterprise automation?
Four stacking layers of automation: the agent loop (executes tasks), the verification loop (self-corrects without human review), the event-driven loop (triggers automatically on system events), and the hill-climbing loop (analyzes its own failures and rewrites its configuration). Together they make the agent improve continuously without manual reprogramming.
Why is prompt engineering no longer sufficient for scaling enterprise AI agents?
Prompt engineering assumes a human reviews and adjusts prompts after each run. At scale that doesn't work. The four loops replace that human intervention with automatic verification, event-based execution, and autonomous improvement based on the history of prior runs.
How does the autonomous self-improvement loop work in an AI agent system?
Every agent execution leaves a trace with results, errors, and quality metrics. An analysis agent reads those traces, identifies recurring failure patterns, and rewrites the prompt and configuration of the main agent. The next day, the agent starts with an improved version of its own instructions, with no human having touched the code.
What is the difference between a four-loop AI agent and a standard enterprise chatbot?
A chatbot responds when someone calls it, using prompts a human wrote. A four-loop agent triggers on events, verifies its own output against quality criteria, and improves its instructions over time. The difference isn't the model, it's the control system built around the model.
Newsletter
Get the best articles in your inbox
We respect your privacy. Unsubscribe anytime.